Letting the translator look back.
Before 2014, a translation model had to squeeze a whole sentence into one short note and translate from memory. Attention let it look back at the words while it wrote. We trained both kinds and watched.
Scroll to cross the river ↓
Translate this.
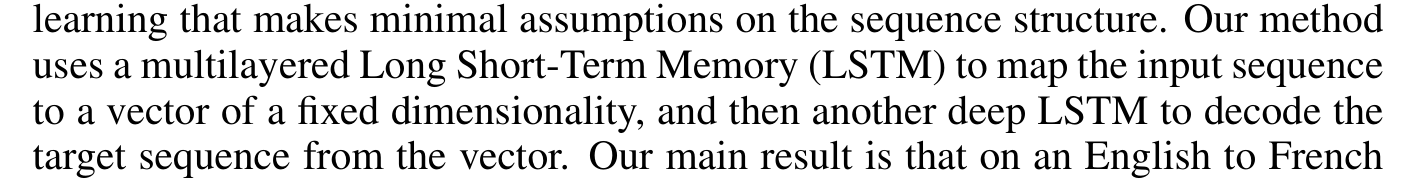
Sutskever, Vinyals & Le · Sequence to Sequence Learning with Neural Networks
Everything, in one vector.
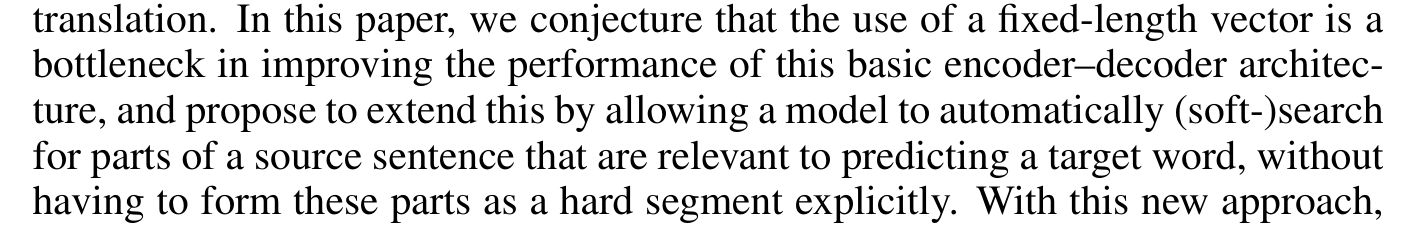
Bahdanau, Cho & Bengio · Neural Machine Translation by Jointly Learning to Align and Translate
Cho, van Merriënboer, Bahdanau & Bengio · On the Properties of Neural Machine Translation
The alignment grid
Longer sentences, one note: it breaks.
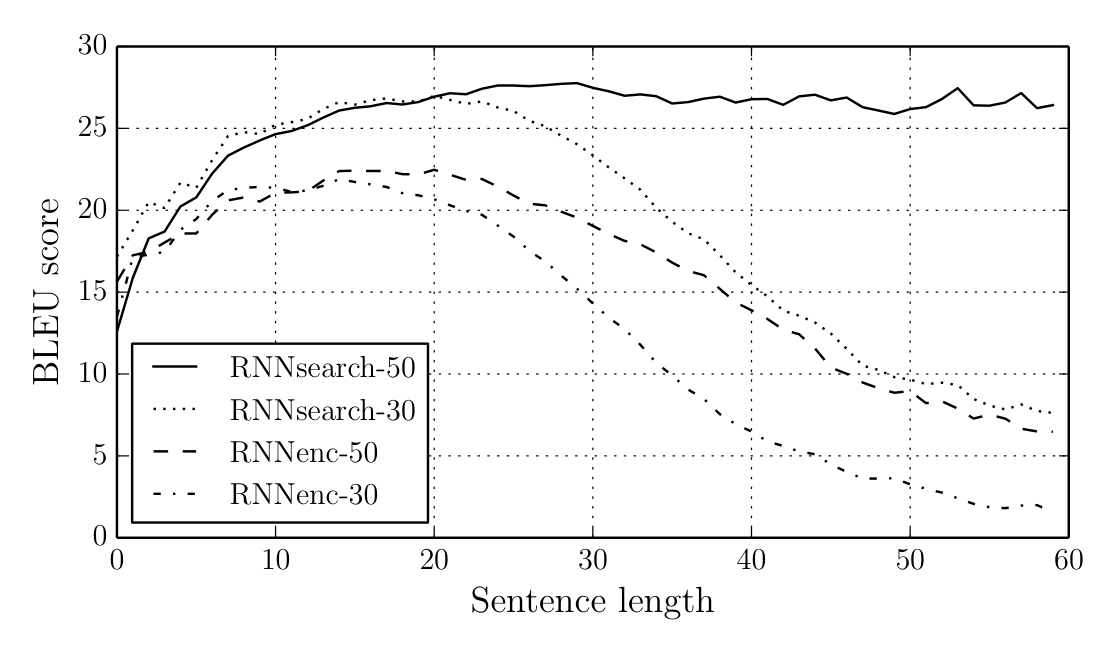
Bahdanau, Cho & Bengio · Neural Machine Translation by Jointly Learning to Align and Translate
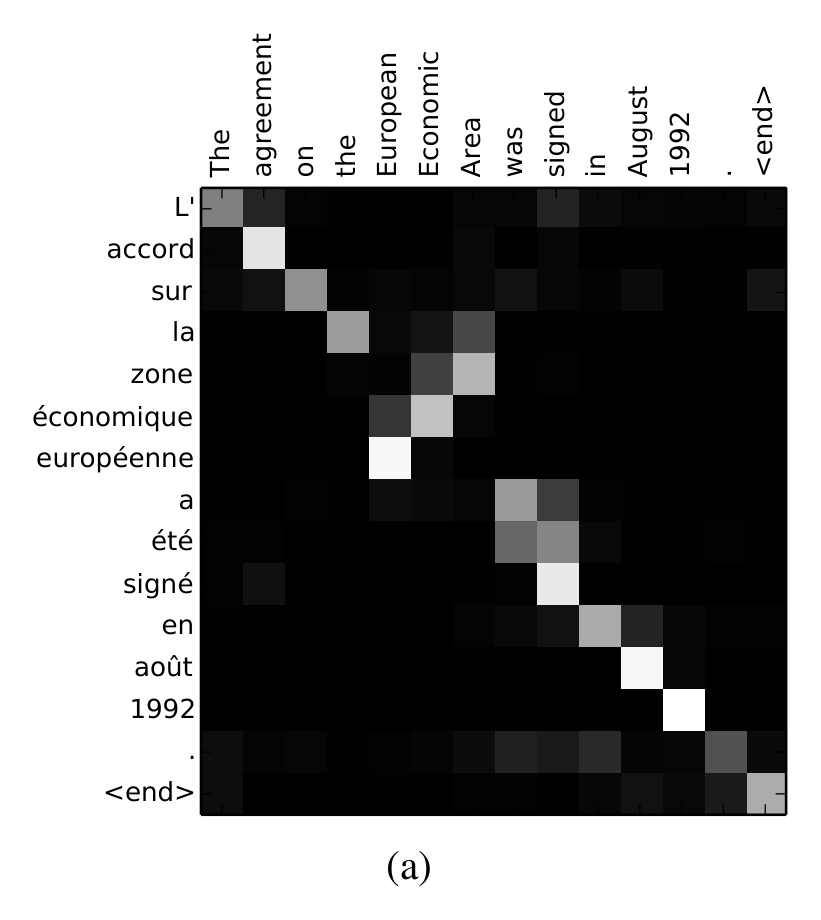
Bahdanau, Cho & Bengio · Figure 3
Jain & Wallace · Attention is not Explanation · Wiegreffe & Pinter · Attention is not not Explanation
The grid grows with the square.
Vaswani et al. · Attention Is All You Need
no belt at all!
Don't memorise the sentence. Keep it, and look back.
One fixed note can only hold so much, so long sentences fall apart. Attention keeps every word within reach and decides, at each step, where to look. That one idea, taken all the way, became the Transformer.