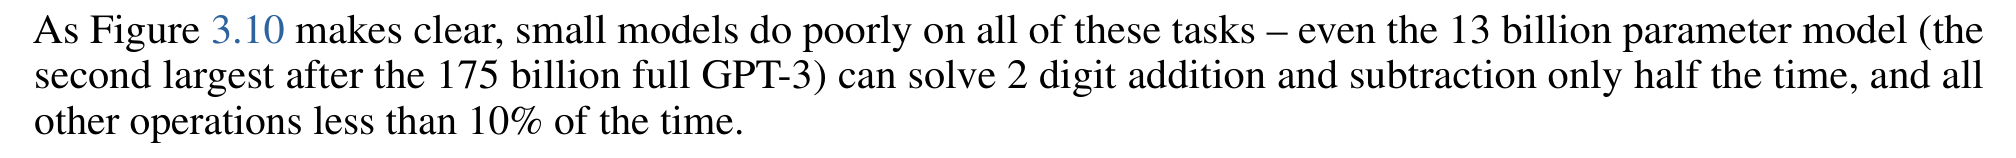
Season one · stop 6 · Emergent abilities

Emergence, or a Change of Ruler

“Bigger models seem to pick up skills out of nowhere. We trained 40 small models on addition and scored the same answers two ways. Some of the jump is the ruler. Some of it is real.”

Unpacking the world: 2.6 MB of drawings and measured data.

AgenticAmit A field guide to emergence

Field guide · emergence

A sudden skill, or a change of ruler?

Bigger models seem to pick up skills out of nowhere. We trained a family of small models on one skill, addition, and scored the very same answers two different ways.

Scroll to walk the ridge ↓

The skill · five-digit addition2,000 test sums
One sum to carry.

The ruler
Pinned · the definitionTMLR 2022
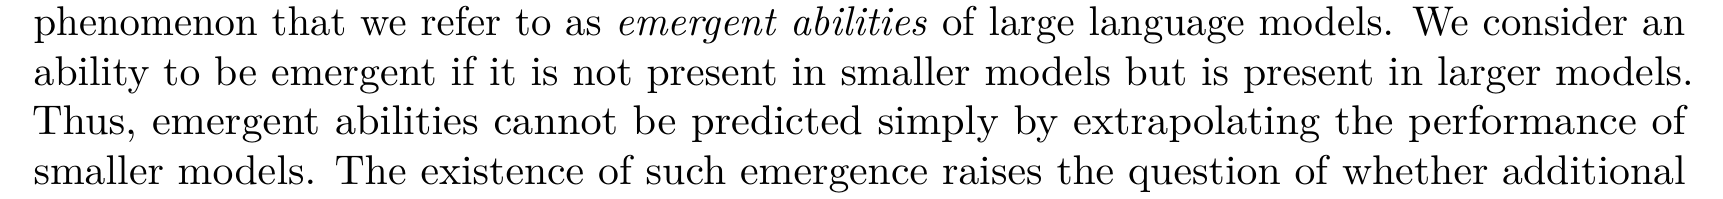
phenomenon that we refer to as emergent abilities of large language models. We consider an ability to be emergent if it is not present in smaller models but is present in larger models. Thus, emergent abilities cannot be predicted simply by extrapolating the performance of smaller models. The existence of such emergence raises the question of whether additional

Wei et al. · Emergent Abilities of Large Language Models

Pinned · GPT-3 doing sumsNeurIPS 2020
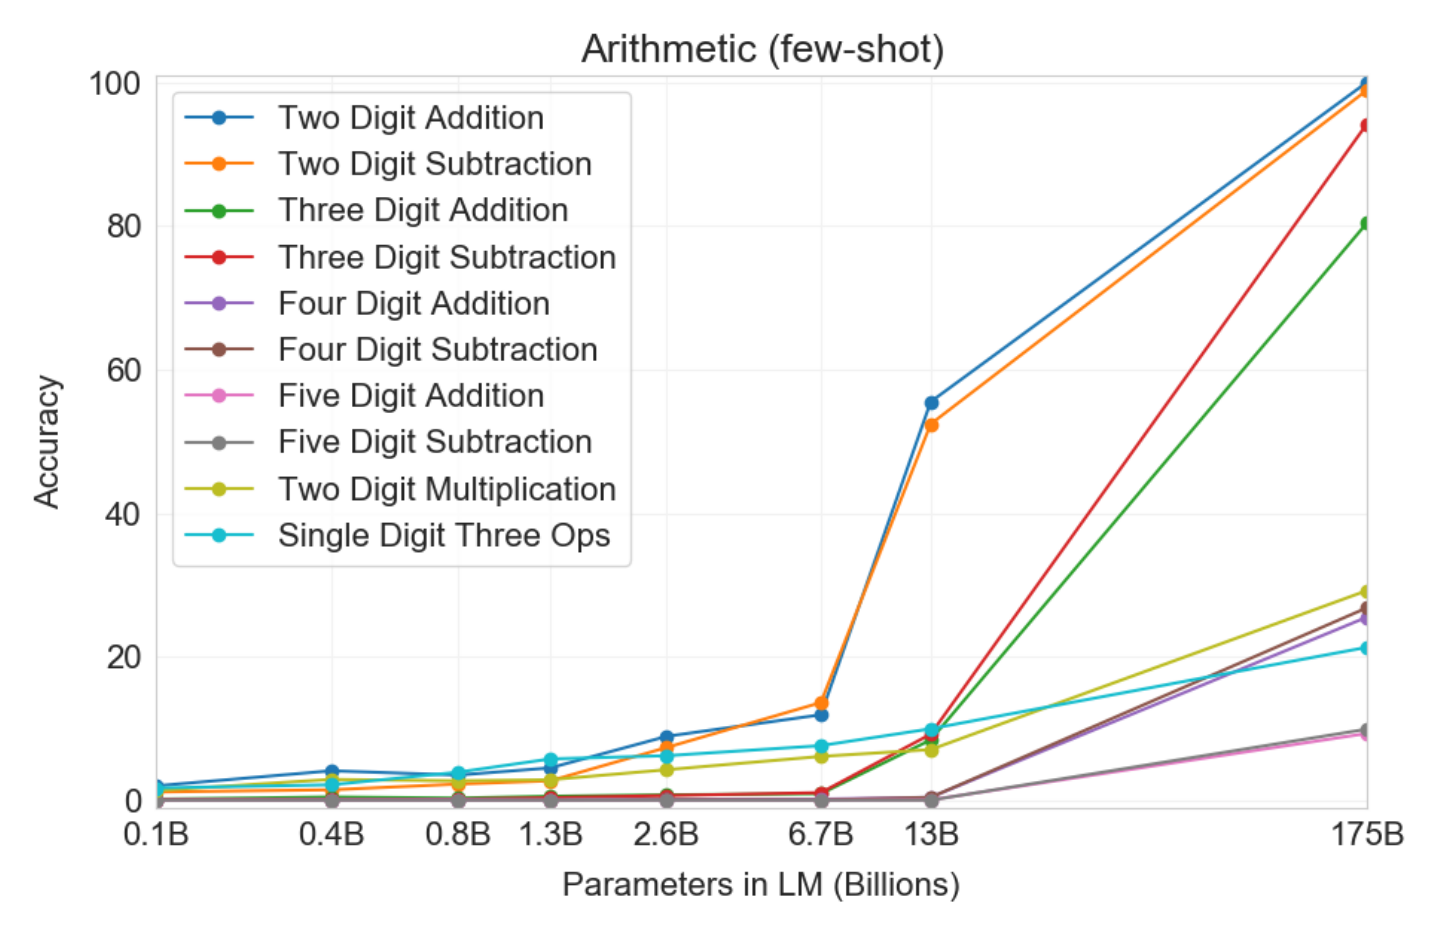
Arithmetic (few-shot) Legend: Two Digit Addition, Two Digit Subtraction, Three Digit Addition, Three Digit Subtraction, Four Digit Addition, Four Digit Subtraction, Five Digit Addition, Five Digit Subtraction, Two Digit Multiplication, Single Digit Three Ops y: Accuracy 0 20 40 60 80 100 x: 0.1B 0.4B 0.8B 1.3B 2.6B 6.7B 13B 175B Parameters in LM (Billions) As Figure 3.10 makes clear, small models do poorly on all of these tasks – even the 13 billion parameter model (the second largest after the 175 billion full GPT-3) can solve 2 digit addition and subtraction only half the time, and all other operations less than 10% of the time.

Brown et al. · Language Models are Few-Shot Learners

Fig. 01 · five digits, all rightour models
All five, or nothing.

Fig. 02 · longer answersarithmetic, not a run
Longer answers, steeper cliffs.

Pinned · the argumentNeurIPS 2023
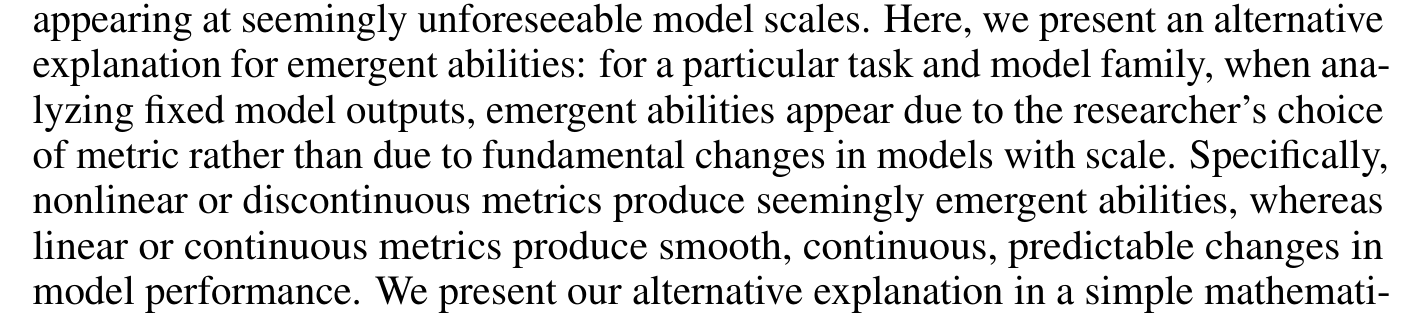
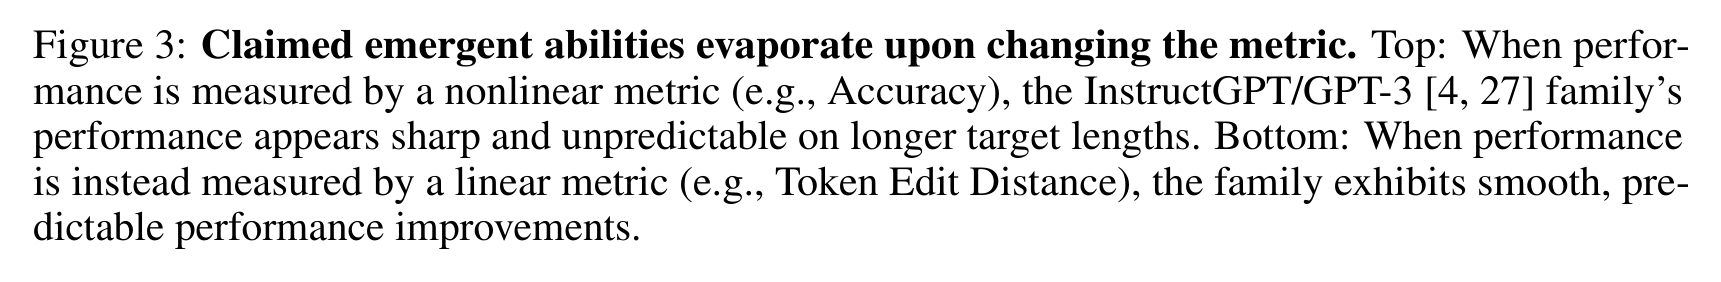
appearing at seemingly unforeseeable model scales. Here, we present an alternative explanation for emergent abilities: for a particular task and model family, when ana- lyzing fixed model outputs, emergent abilities appear due to the researcher’s choice of metric rather than due to fundamental changes in models with scale. Specifically, nonlinear or discontinuous metrics produce seemingly emergent abilities, whereas linear or continuous metrics produce smooth, continuous, predictable changes in model performance. We present our alternative explanation in a simple mathemati-

Schaeffer, Miranda & Koyejo · Are Emergent Abilities of Large Language Models a Mirage?

Pinned · GPT-3, re-scoredNeurIPS 2023
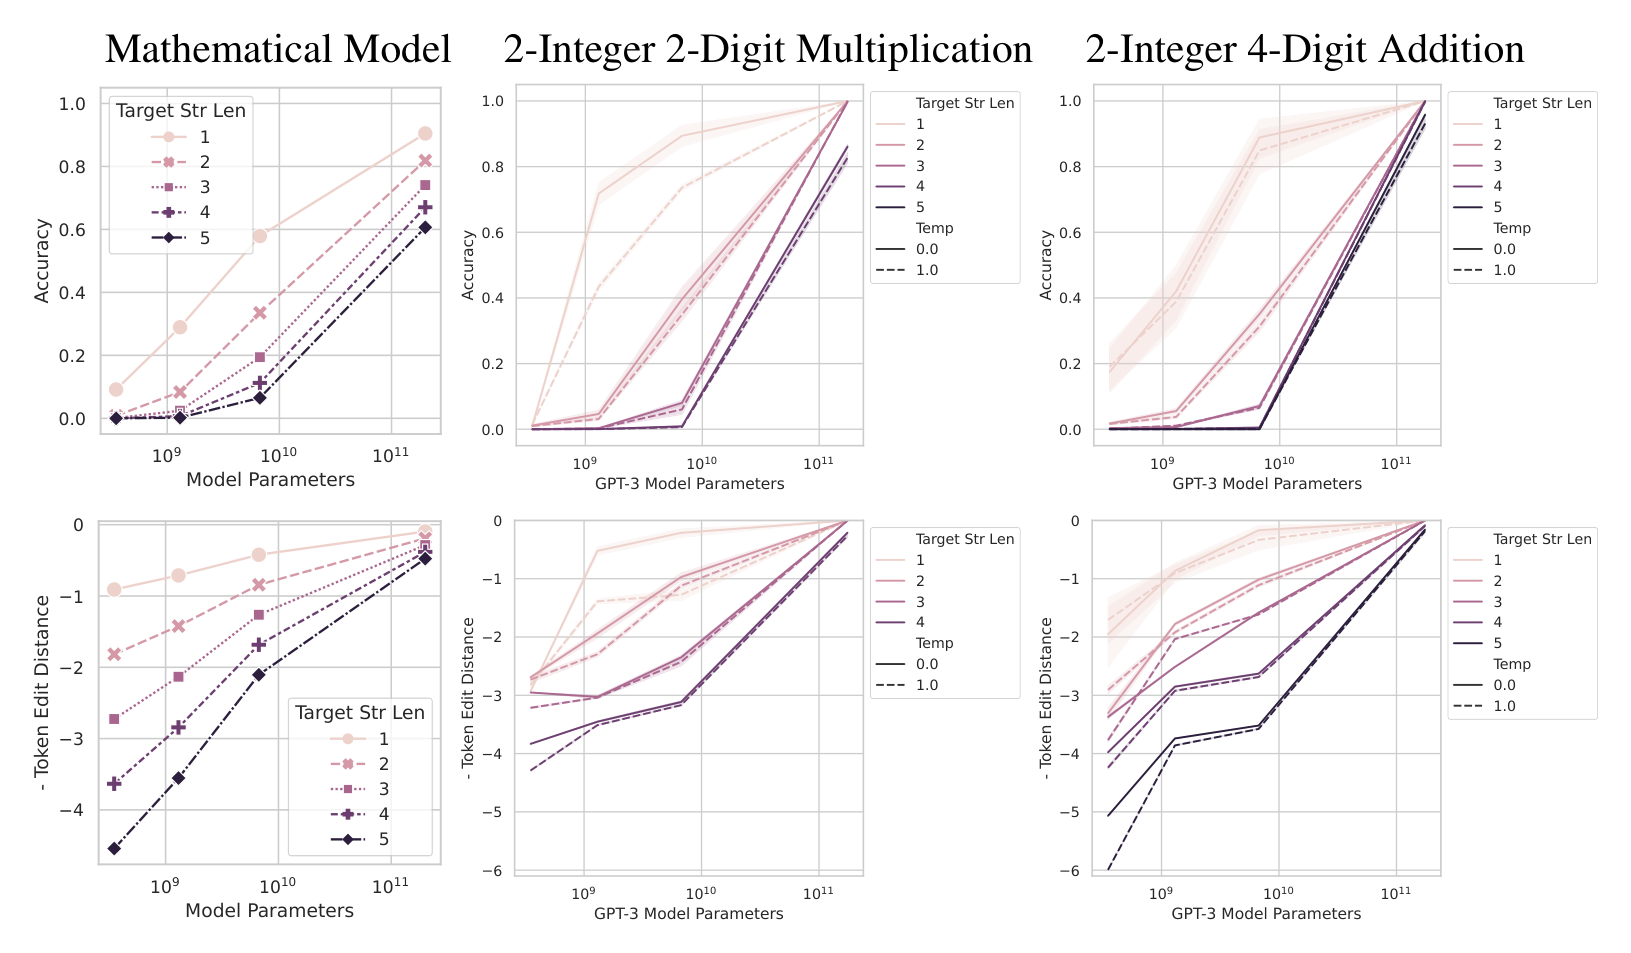
Mathematical Model 2-Integer 2-Digit Multiplication 2-Integer 4-Digit Addition Top row y: Accuracy 0.0–1.0 Bottom row y: - Token Edit Distance (0 to −4 model; 0 to −6 GPT-3) x: Model Parameters (model) / GPT-3 Model Parameters: 10^9 10^10 10^11 Legend: Target Str Len 1 2 3 4 5 (bottom-middle panel lists 1–4); Temp 0.0 / 1.0 Figure 3: Claimed emergent abilities evaporate upon changing the metric. Top: When perfor- mance is measured by a nonlinear metric (e.g., Accuracy), the InstructGPT/GPT-3 [4, 27] family’s performance appears sharp and unpredictable on longer target lengths. Bottom: When performance is instead measured by a linear metric (e.g., Token Edit Distance), the family exhibits smooth, pre- dictable performance improvements.

Schaeffer, Miranda & Koyejo · Figure 3

The catch · run by run5 runs per size
Some of the jump is real.
0% digits right50%100%

Pinned · a tipping pointNeurIPS 2024
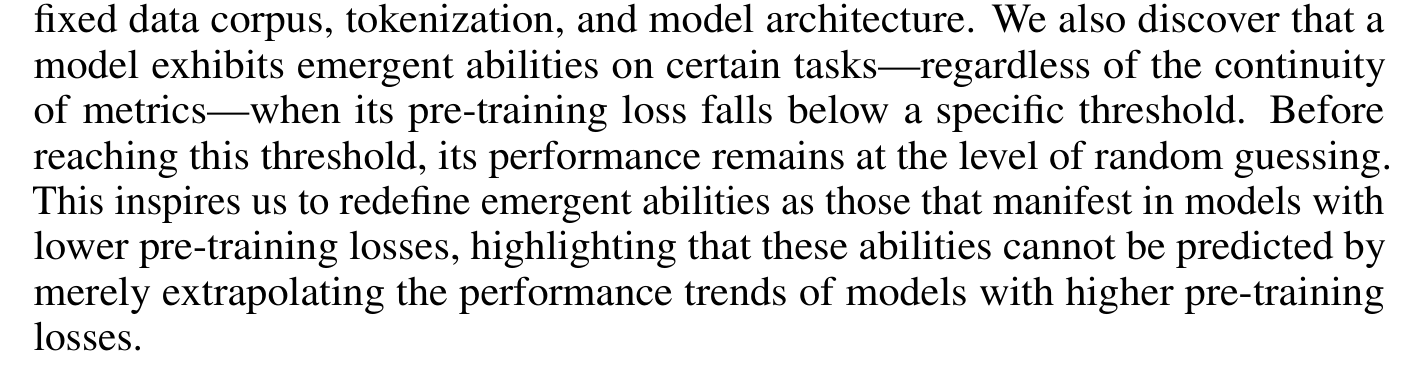
fixed data corpus, tokenization, and model architecture. We also discover that a model exhibits emergent abilities on certain tasks—regardless of the continuity of metrics—when its pre-training loss falls below a specific threshold. Before reaching this threshold, its performance remains at the level of random guessing. This inspires us to redefine emergent abilities as those that manifest in models with lower pre-training losses, highlighting that these abilities cannot be predicted by merely extrapolating the performance trends of models with higher pre-training losses.

Du, Zeng, Dong & Tang · Emergent Abilities from the Loss Perspective

Pinned · the authors' own limitNeurIPS 2023

This paper has several limitations. First, nothing in this paper should be interpreted as claiming that large language models cannot display emergent abilities; rather, our message is that some previously claimed emergent abilities appear to be mirages induced by researcher analyses. Second,

Schaeffer, Miranda & Koyejo · §6 Limitations

Pinned · a benchmark says it tooBIG-bench
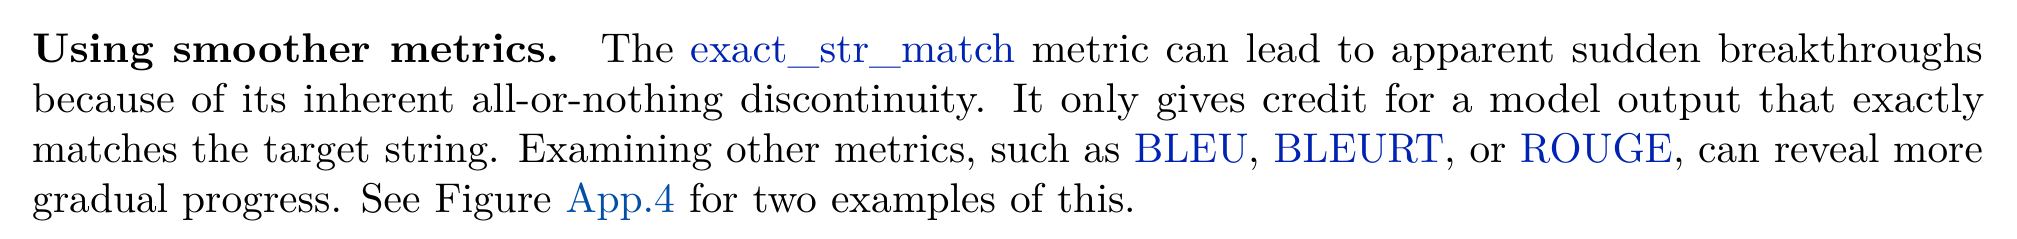
Using smoother metrics. The exact_str_match metric can lead to apparent sudden breakthroughs because of its inherent all-or-nothing discontinuity. It only gives credit for a model output that exactly matches the target string. Examining other metrics, such as BLEU, BLEURT, or ROUGE, can reveal more gradual progress. See Figure App.4 for two examples of this.

Srivastava et al. · Beyond the Imitation Game (BIG-bench)

Carry thisone question
How was it scored?

Take this with you

A cliff can be the ground, or the ruler you measured it with.
Amit, settled on an answer